Industrial plants normally operate within recognisable patterns.
Temperatures rise and fall in expected ways.
Pressures change with throughput.
Equipment behaves differently during startup, steady operation and shutdown.
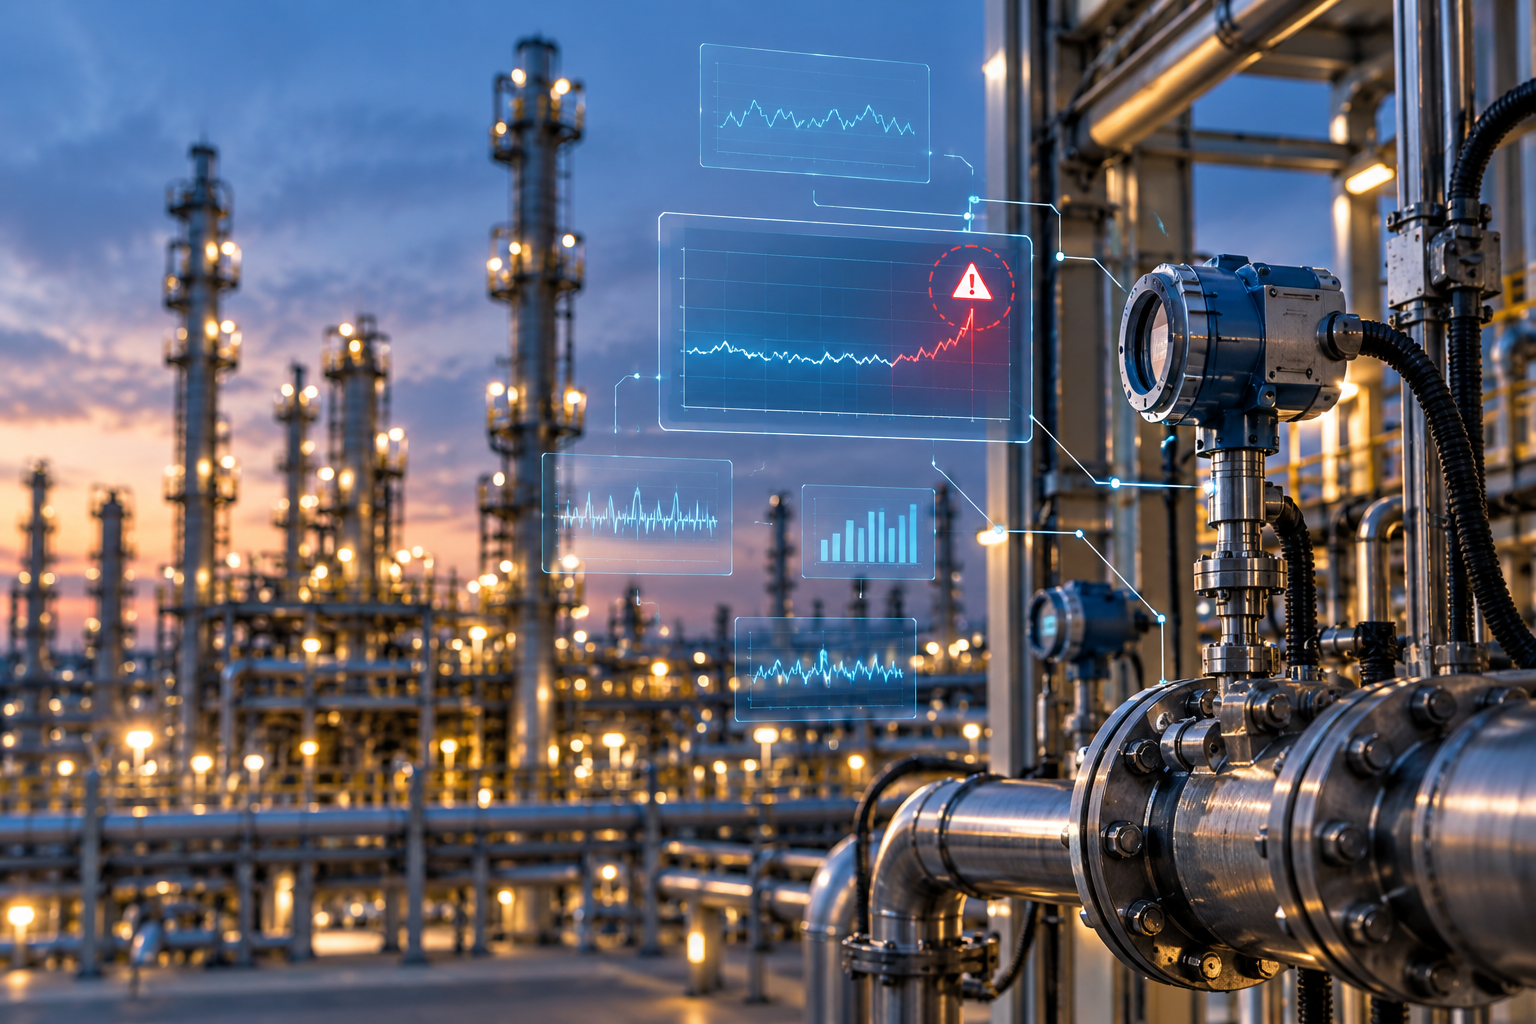
Anomaly detection tries to identify when plant behaviour begins to move away from those normal patterns.
Traditional alarms often work by comparing a measured value with a defined limit.
For example:
This approach is essential, but it may not detect every developing problem early.
A parameter may still remain within its alarm limit while behaving differently from normal.
For example:
Anomaly detection can look for these changes in behaviour.
A single process variable may not look unusual.
But the relationship between several variables may be abnormal.
Analytics can compare combinations of:
This can reveal patterns that are difficult to detect manually.
The same reading may be normal in one operating condition and abnormal in another.
A model therefore needs to consider whether the plant is:
Without context, normal transitions may generate false alerts.
If an anomaly system generates too many unnecessary warnings, operators may stop paying attention.
Good implementation therefore requires careful tuning.
The objective is not to detect every small variation.
It is to highlight changes that are meaningful enough to justify attention.
An anomaly alert tells the team:
“Something is behaving differently.”
It does not always explain why.
Operators and engineers still need to investigate the process, equipment and instrumentation.
The value of anomaly detection lies in earlier awareness.
If plant teams can recognise abnormal behaviour before it becomes a major alarm or failure, they have more time to understand and manage the situation.